Where does the LLM call sit in the architecture?
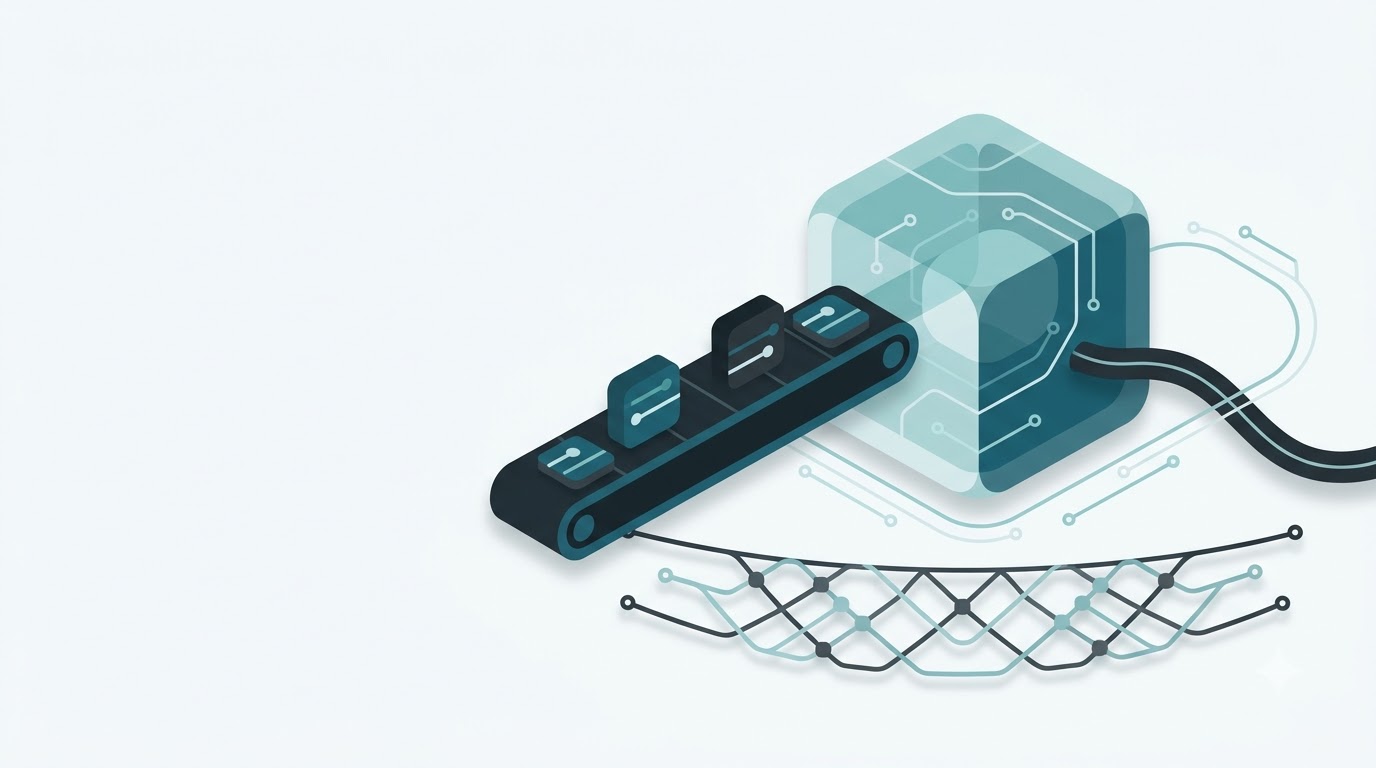
Keep the AI call out of the main request path whenever you can. Send the work to a background queue, return quickly to the user, and update the screen when the result is ready. This keeps your app responsive even when the AI service is slow, and it lets you retry safely.
In a Laravel application, that usually means a queued job that calls a small service class, with the result stored and then shown to the user. Keep the AI provider behind your own interface so you can switch providers later without touching the rest of the app.
How do you control cost?
- Set a spending limit per user, per customer and overall, with an alert before you hit it.
- Limit input size. Trim long text to what the task needs.
- Cache repeated requests so identical questions are not paid for twice.
- Use the smallest option that does the job for simple tasks.
- Track usage by feature so you can see what each one costs.
Prices and limits change often, so check your provider’s current terms and review costs monthly.
How do you handle failures and timeouts?
Assume the service will sometimes be slow, unavailable or return nonsense.
- Set sensible timeouts.
- Retry with growing delays, and stop after a fixed number of attempts.
- Make jobs safe to repeat so a retry never creates duplicate results.
- Show the user a clear message when the feature is unavailable.
Planning an AI feature for your product? Tell us what you are building and we will give you a clear scope and an honest view on risk.
What should the fallback be?
How do you check the quality of the output?
- Validate the output format before using it. Reject anything that does not match the structure you expect.
- Keep a small set of real examples and re-run them whenever you change a prompt or provider.
- Store a version number with each prompt so you can trace a bad result to its cause.
- Route low-confidence or unusual results to a person.
Frequently Asked Questions
How do you handle data privacy?
What should you build first?
Our AI development team and web development team can help add AI features to an existing product in a controlled way.